Hyperparameter Tuning with KerasTuner: Keras 3#
Hyperparameters are the choices made before training: here the number of
filters in each convolution layer, the width of the dense layer, and the
learning rate. A tuner trains one model per configuration and keeps the
configuration with the best validation accuracy. The test set plays no part
in the search; it scores the selected configuration once at the end. Reduce
TRIALS or SEARCH_EPOCHS for a quicker run.
Keras and PyTorch#
This notebook repeats the PyTorch version with the Keras 3 API, running on
the same PyTorch backend. compile() sets the optimizer and loss, fit()
runs the loop over batches and epochs, and callbacks such as early stopping
replace hand-written control flow. The data split, model, and evaluation
match the PyTorch notebook.
Setup#
The libraries used below.
Keras 3.15.1, backend torch, PyTorch 2.13.0+cu130
Load MNIST and split it#
The 60,000 official training images are split, with a fixed seed and stratified by class, into 50,000 for training and 10,000 for validation. The 10,000 official test images are used once, at the end.
SEED = 42
BATCH_SIZE = 128
CLASS_NAMES = ['0', '1', '2', '3', '4', '5', '6', '7', '8', '9']

keras.utils.set_random_seed(SEED)
torch.use_deterministic_algorithms(True, warn_only=True)

(x_development, y_development), (x_test, y_test) = keras.datasets.mnist.load_data()
all_indices = np.arange(len(y_development))
train_indices, validation_indices = train_test_split(
    all_indices,
    test_size=10000,
    random_state=SEED,
    stratify=y_development,
)
split_signature = hashlib.sha256(
    validation_indices.astype("<i8").tobytes()
).hexdigest()[:16]

# Scale pixel values from 0-255 to 0-1.
x_train = x_development[train_indices].astype("float32") / 255.0
y_train = y_development[train_indices].astype(np.int64)
x_validation = x_development[validation_indices].astype("float32") / 255.0
y_validation = y_development[validation_indices].astype(np.int64)
x_test = x_test.astype("float32") / 255.0
y_test = y_test.astype(np.int64)
x_train = x_train[..., np.newaxis]
x_validation = x_validation[..., np.newaxis]
x_test = x_test[..., np.newaxis]

assert set(train_indices).isdisjoint(validation_indices)
print(
    f"train={len(y_train):,}, validation={len(y_validation):,}, "
    f"test={len(y_test):,}, image shape={x_train.shape[1:]}"
)
train=50,000, validation=10,000, test=10,000, image shape=(28, 28, 1)
Training loop#
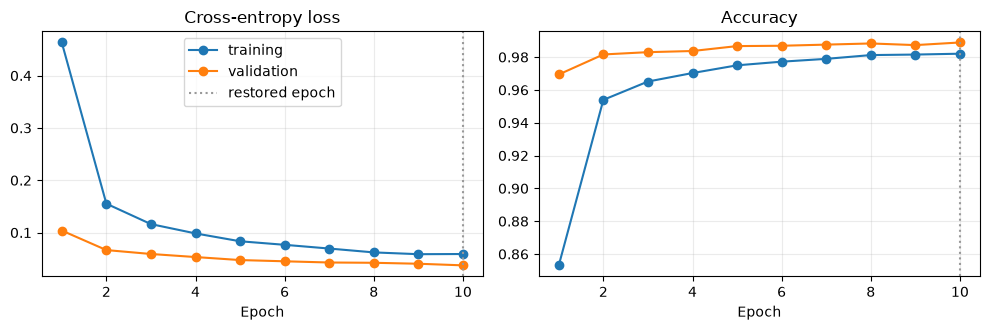
fit() below compiles the model with the Adam optimizer and the
cross-entropy loss, trains it, and uses a callback to restore the weights
from the epoch with the best validation accuracy.
def fit(model, epochs, learning_rate=1e-3, train=None, validation=None, verbose=True):
    # Train with Adam and restore the epoch with the best validation accuracy.
    model.compile(
        optimizer=keras.optimizers.Adam(learning_rate),
        loss=keras.losses.SparseCategoricalCrossentropy(from_logits=True),
        metrics=["accuracy"],
    )
    keep_best = keras.callbacks.EarlyStopping(
        monitor="val_accuracy", mode="max", patience=epochs, restore_best_weights=True
    )
    history = model.fit(
        *(train or (x_train, y_train)),
        validation_data=validation or (x_validation, y_validation),
        epochs=epochs,
        batch_size=BATCH_SIZE,
        callbacks=[keep_best],
        verbose=2 if verbose else 0,
    ).history
    if verbose:
        best_epoch = int(np.argmax(history["val_accuracy"]))
        print(
            f"restored epoch {best_epoch + 1} "
            f"(validation accuracy {history['val_accuracy'][best_epoch]:.4f})"
        )
    return history


def predict_classes(model, images):
    return model.predict(images, batch_size=BATCH_SIZE, verbose=0).argmax(axis=1)


def plot_history(history, title=None):
    epochs = np.arange(1, len(history["loss"]) + 1)
    best = epochs[int(np.argmax(history["val_accuracy"]))]
    fig, axes = plt.subplots(1, 2, figsize=(10, 3.4))
    for axis, key, label in zip(axes, ("loss", "accuracy"), ("Cross-entropy loss", "Accuracy")):
        axis.plot(epochs, history[key], marker="o", label="training")
        axis.plot(epochs, history[f"val_{key}"], marker="o", label="validation")
        axis.axvline(best, color="0.6", linestyle=":", label="restored epoch")
        axis.set(title=label, xlabel="Epoch")
        axis.grid(alpha=0.25)
    axes[0].legend()
    if title:
        fig.suptitle(title)
    plt.tight_layout()
    plt.show()
The search space#
Every combination of the choices below defines one candidate model, 24 in
all. The budget allows TRIALS of them, each trained for up to
SEARCH_EPOCHS epochs and scored by its best validation accuracy.
KerasTuner’s random search draws configurations uniformly.
TRIALS = 4  # Reduce to 2 for a quicker search.
SEARCH_EPOCHS = 10  # Reduce to 1 or 2 for quicker trials.
SEARCH_SPACE = {
    "filters_1": [16, 32],
    "filters_2": [32, 64],
    "dense_units": [100, 200],
    "learning_rate": [1e-2, 1e-3, 1e-4],
}
Run the search with KerasTuner#
def build_model(hp):
    return keras.Sequential(
        [
            keras.Input(shape=(28, 28, 1)),
            layers.Conv2D(hp.Choice("filters_1", SEARCH_SPACE["filters_1"]), 3, activation="relu"),
            layers.MaxPooling2D(),
            layers.Conv2D(hp.Choice("filters_2", SEARCH_SPACE["filters_2"]), 3, activation="relu"),
            layers.MaxPooling2D(),
            layers.Dropout(0.25),
            layers.Flatten(),
            layers.Dense(hp.Choice("dense_units", SEARCH_SPACE["dense_units"]), activation="relu"),
            layers.Dropout(0.5),
            layers.Dense(10),
        ]
    )


class CompiledHyperModel(kt.HyperModel):
    def build(self, hp):
        model = build_model(hp)
        model.compile(
            optimizer=keras.optimizers.Adam(hp.Choice("learning_rate", SEARCH_SPACE["learning_rate"])),
            loss=keras.losses.SparseCategoricalCrossentropy(from_logits=True),
            metrics=["accuracy"],
        )
        return model


tuner = kt.RandomSearch(
    CompiledHyperModel(),
    objective="val_accuracy",
    max_trials=TRIALS,
    seed=SEED,
    overwrite=True,
    directory=str(Path(os.getenv("HELIO_TUNER_DIR", "/tmp")) / "helio-keras-tuner"),
    project_name="mnist-cnn",
)
tuner.search(
    x_train,
    y_train,
    validation_data=(x_validation, y_validation),
    epochs=SEARCH_EPOCHS,
    batch_size=BATCH_SIZE,
    verbose=0,
)
trials = pd.DataFrame(
    [
        {**trial.hyperparameters.values, "best validation accuracy": trial.score}
        for trial in tuner.oracle.get_best_trials(TRIALS)
    ]
)
display(trials.round(4))
best_parameters = tuner.get_best_hyperparameters(1)[0]
| filters_1 | filters_2 | dense_units | learning_rate | best validation accuracy | |
|---|---|---|---|---|---|
| 0 | 32 | 32 | 100 | 0.001 | 0.9906 |
| 1 | 16 | 32 | 200 | 0.001 | 0.9882 |
| 2 | 32 | 32 | 100 | 0.010 | 0.9875 |
| 3 | 32 | 32 | 200 | 0.010 | 0.9865 |
Retrain the selected configuration and evaluate once#
The selected configuration is retrained from scratch with the same epoch budget, the best validation epoch is restored, and the model is scored on the test set.
keras.utils.set_random_seed(SEED)
model = build_model(best_parameters)
history = fit(model, SEARCH_EPOCHS, learning_rate=best_parameters.get("learning_rate"))
plot_history(history)
Epoch 1/10
391/391 - 11s - 28ms/step - accuracy: 0.8531 - loss: 0.4633 - val_accuracy: 0.9694 - val_loss: 0.1040
Epoch 2/10
391/391 - 11s - 28ms/step - accuracy: 0.9539 - loss: 0.1553 - val_accuracy: 0.9816 - val_loss: 0.0666
Epoch 3/10
391/391 - 12s - 30ms/step - accuracy: 0.9651 - loss: 0.1162 - val_accuracy: 0.9830 - val_loss: 0.0591
Epoch 4/10
391/391 - 11s - 29ms/step - accuracy: 0.9703 - loss: 0.0985 - val_accuracy: 0.9837 - val_loss: 0.0533
Epoch 5/10
391/391 - 11s - 28ms/step - accuracy: 0.9750 - loss: 0.0834 - val_accuracy: 0.9867 - val_loss: 0.0475
Epoch 6/10
391/391 - 11s - 28ms/step - accuracy: 0.9772 - loss: 0.0767 - val_accuracy: 0.9869 - val_loss: 0.0452
Epoch 7/10
391/391 - 11s - 28ms/step - accuracy: 0.9789 - loss: 0.0695 - val_accuracy: 0.9876 - val_loss: 0.0429
Epoch 8/10
391/391 - 11s - 29ms/step - accuracy: 0.9812 - loss: 0.0622 - val_accuracy: 0.9883 - val_loss: 0.0423
Epoch 9/10
391/391 - 11s - 28ms/step - accuracy: 0.9815 - loss: 0.0588 - val_accuracy: 0.9873 - val_loss: 0.0405
Epoch 10/10
391/391 - 11s - 28ms/step - accuracy: 0.9821 - loss: 0.0591 - val_accuracy: 0.9889 - val_loss: 0.0374
restored epoch 10 (validation accuracy 0.9889)
Evaluate on the test set#
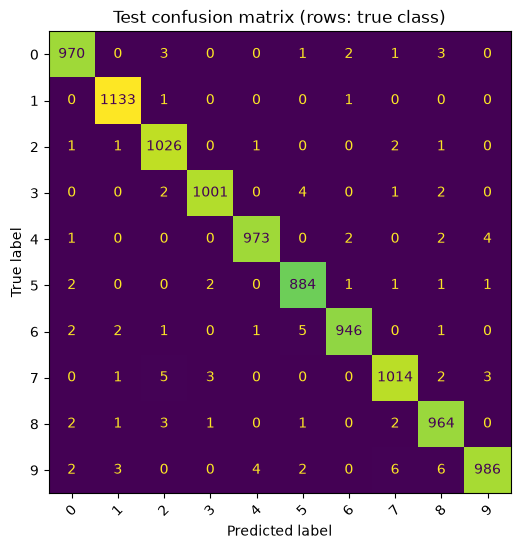
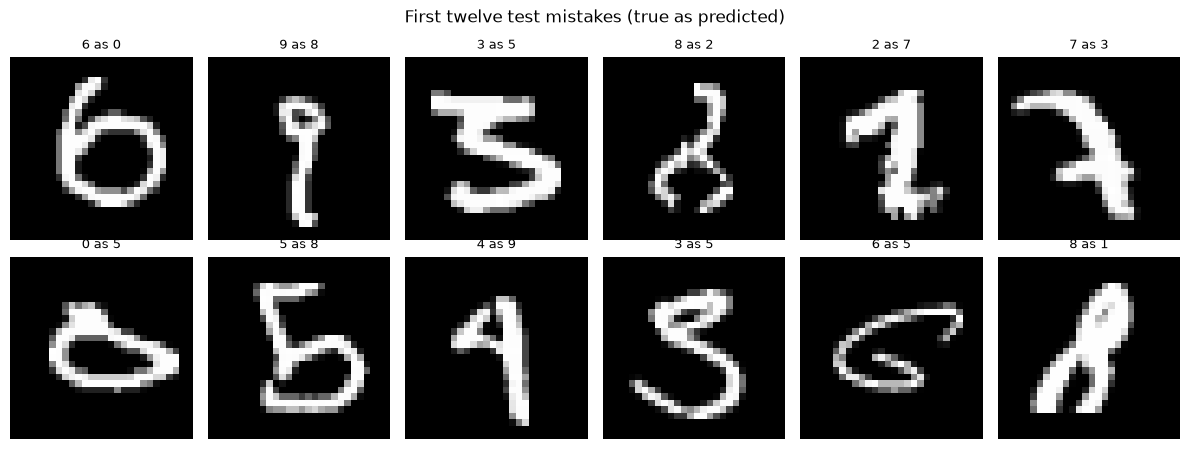
The first twelve test mistakes follow the confusion matrix.
def as_image(sample):
    # Convert one stored sample to (height, width[, channel]) for plotting.
    if sample.ndim == 1:
        sample = sample.reshape(28, 28)
    if sample.ndim == 3 and sample.shape[0] in (1, 3):
        sample = np.transpose(sample, (1, 2, 0))
    return sample.squeeze()


test_predictions = predict_classes(model, x_test)
test_accuracy = accuracy_score(y_test, test_predictions)
cm = confusion_matrix(y_test, test_predictions, labels=np.arange(10))
print(f"test accuracy: {test_accuracy:.4f}")
print(
    classification_report(
        y_test, test_predictions, labels=np.arange(10),
        target_names=CLASS_NAMES, digits=3, zero_division=0,
    )
)

fig, ax = plt.subplots(figsize=(7, 6))
ConfusionMatrixDisplay(cm, display_labels=CLASS_NAMES).plot(
    ax=ax, colorbar=False, values_format="d", xticks_rotation=45
)
ax.set_title("Test confusion matrix (rows: true class)")
plt.show()

mistakes = np.flatnonzero(test_predictions != y_test)[:12]
fig, axes = plt.subplots(2, 6, figsize=(12, 4.6))
for axis in axes.flat:
    axis.axis("off")
for axis, index in zip(axes.flat, mistakes):
    image = as_image(x_test[index])
    axis.imshow(image, cmap="gray" if image.ndim == 2 else None)
    axis.set_title(f"{CLASS_NAMES[y_test[index]]} as {CLASS_NAMES[test_predictions[index]]}", fontsize=9)
fig.suptitle("First twelve test mistakes (true as predicted)")
plt.tight_layout()
plt.show()
test accuracy: 0.9897
              precision    recall  f1-score   support

           0      0.990     0.990     0.990       980
           1      0.993     0.998     0.996      1135
           2      0.986     0.994     0.990      1032
           3      0.994     0.991     0.993      1010
           4      0.994     0.991     0.992       982
           5      0.986     0.991     0.988       892
           6      0.994     0.987     0.991       958
           7      0.987     0.986     0.987      1028
           8      0.982     0.990     0.986       974
           9      0.992     0.977     0.985      1009

    accuracy                          0.990     10000
   macro avg      0.990     0.990     0.990     10000
weighted avg      0.990     0.990     0.990     10000
What the results show#
On MNIST the configurations differ by fractions of a percent once the learning rate is reasonable, so the search mainly rules out the learning rates that are too high or too low. With four trials the ranking of the remaining configurations is not reliable: the differences are comparable to the change caused by a new random seed. A larger budget, or repeated trials per configuration, is needed before a small difference means anything.
Try it yourself in Keras#
Change one choice at a time and keep the data split and evaluation unchanged:
rerun the search with a different sampler seed and see whether the same configuration wins.
increase
TRIALSto 12 and check how much the best validation accuracy improves.add dropout rates to the search space.