Dense Neural Network for MNIST: PyTorch#
A neural network is a chain of simple functions with adjustable weights.
Training adjusts those weights so the network’s output for each input moves
closer to the known answer. This notebook trains a small dense network to
recognize handwritten digits from the MNIST collection, and goes through each
step: preparing the data, defining the network, the training loop, and an
honest evaluation. The Neural Networks chapter gives an
overview; the Keras 3 version runs the same model through fit().
Training runs for five epochs, about a minute on a laptop CPU. Set EPOCHS
to 1 or 2 in the data cell for a quicker run.
Setup#
The libraries used below.
PyTorch 2.13.0+cu130
Load MNIST and split it#
MNIST contains 70,000 grayscale images of handwritten digits, 28×28 pixels each, divided by its authors into 60,000 training and 10,000 test images. We split the training images again, with a fixed seed and stratified by digit:
50,000 training images, used to fit the weights;
10,000 validation images, used to watch for overfitting while we make choices about the model;
the 10,000 official test images, used once, after all choices are made, to estimate how the model will do on new digits.
SEED = 42
EPOCHS = 5  # Reduce to 1 or 2 for a quicker run.
BATCH_SIZE = 128  # Images per weight update.

random.seed(SEED)
np.random.seed(SEED)
torch.manual_seed(SEED)
os.environ.setdefault("CUBLAS_WORKSPACE_CONFIG", ":4096:8")  # Deterministic cuBLAS on GPUs.
torch.use_deterministic_algorithms(True, warn_only=True)
DEVICE = torch.device(
    "cuda" if torch.cuda.is_available()
    else "mps" if torch.backends.mps.is_available()
    else "cpu"
)
print(f"device: {DEVICE}")

data_root = Path(os.getenv("HELIO_DATA_DIR", Path.home() / ".cache" / "helio-data-methods"))
development_dataset = datasets.MNIST(data_root, train=True, download=True)
test_dataset = datasets.MNIST(data_root, train=False, download=True)
x_development = development_dataset.data.numpy()
y_development = development_dataset.targets.numpy()
x_test = test_dataset.data.numpy()
y_test = test_dataset.targets.numpy()

all_indices = np.arange(len(y_development))
train_indices, validation_indices = train_test_split(
    all_indices,
    test_size=10_000,
    random_state=SEED,
    stratify=y_development,
)
split_signature = hashlib.sha256(
    validation_indices.astype("<i8").tobytes()
).hexdigest()[:16]

# Scale pixel values from 0-255 to 0-1.
x_train = x_development[train_indices].astype("float32") / 255.0
y_train = y_development[train_indices]
x_validation = x_development[validation_indices].astype("float32") / 255.0
y_validation = y_development[validation_indices]
x_test = x_test.astype("float32") / 255.0

assert set(train_indices).isdisjoint(validation_indices)
print(
    f"train={len(y_train):,}, validation={len(y_validation):,}, "
    f"test={len(y_test):,}, image shape={x_train.shape[1:]}"
)
device: cpu
train=50,000, validation=10,000, test=10,000, image shape=(28, 28)
Look at the data#
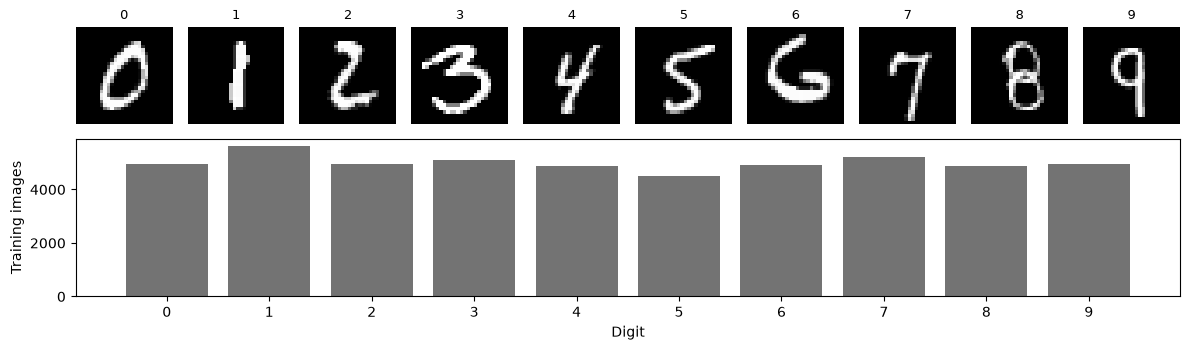
One example of each digit and the number of training images per digit. The classes are nearly balanced, so accuracy is a fair summary of performance.
fig = plt.figure(figsize=(12, 3.6))
grid = fig.add_gridspec(2, 10, height_ratios=[1, 1.2])
for digit in range(10):
    axis = fig.add_subplot(grid[0, digit])
    axis.imshow(x_train[np.flatnonzero(y_train == digit)[0]], cmap="gray")
    axis.set_title(str(digit), fontsize=9)
    axis.axis("off")
counts_axis = fig.add_subplot(grid[1, :])
counts_axis.bar(np.arange(10), np.bincount(y_train, minlength=10), color="0.45")
counts_axis.set(xticks=np.arange(10), xlabel="Digit", ylabel="Training images")
plt.tight_layout()
plt.show()
Batch the data#
A DataLoader serves the images in batches of 128, reshuffling the
training images every epoch so that consecutive updates see different
digits.
def make_loader(images, labels, shuffle=False):
    dataset = TensorDataset(torch.from_numpy(images), torch.from_numpy(labels).long())
    generator = torch.Generator().manual_seed(SEED) if shuffle else None
    return DataLoader(dataset, batch_size=BATCH_SIZE, shuffle=shuffle, generator=generator)


# Shuffle the training images each epoch; keep validation and test in order.
train_loader = make_loader(x_train, y_train, shuffle=True)
validation_loader = make_loader(x_validation, y_validation)
test_loader = make_loader(x_test, y_test)
images, labels = next(iter(train_loader))
print(f"one batch: images {tuple(images.shape)}, labels {tuple(labels.shape)}")
one batch: images (128, 28, 28), labels (128,)
Define the network#
The network flattens each image into 784 numbers and passes them through two dense layers of 200 and 150 units. Each unit computes a weighted sum of its inputs plus a bias and applies the ReLU function, \(\max(0, x)\); without such nonlinearities a stack of layers would reduce to a single linear map. Dropout sets half of the second layer’s outputs to zero at random during training, which discourages the network from relying on any one unit. The last layer has ten outputs, the logits: unnormalized scores, one per digit, which a softmax turns into probabilities.
The loss is the cross-entropy, the negative log of the probability the network assigns to the correct digit. Adam is the optimizer: a variant of gradient descent that adapts the step size for each weight.
DROPOUT_RATE = 0.5
model = nn.Sequential(
    nn.Flatten(),
    nn.Linear(28 * 28, 200),
    nn.ReLU(),
    nn.Linear(200, 150),
    nn.ReLU(),
    nn.Dropout(DROPOUT_RATE),
    nn.Linear(150, 10),
).to(DEVICE)
loss_function = nn.CrossEntropyLoss()
optimizer = torch.optim.Adam(model.parameters())
print(model)
print(f"trainable parameters: {sum(p.numel() for p in model.parameters()):,}")
Sequential(
  (0): Flatten(start_dim=1, end_dim=-1)
  (1): Linear(in_features=784, out_features=200, bias=True)
  (2): ReLU()
  (3): Linear(in_features=200, out_features=150, bias=True)
  (4): ReLU()
  (5): Dropout(p=0.5, inplace=False)
  (6): Linear(in_features=150, out_features=10, bias=True)
)
trainable parameters: 188,660
Train#
An epoch is one pass over the training images. Within an epoch the images arrive in batches of 128, and for each batch the loop performs four steps, marked in the code:
the forward pass computes the logits;
the loss compares them with the true labels;
loss.backward()computes the gradient of the loss with respect to every weight (backpropagation);optimizer.step()moves each weight a small step against its gradient.
After each epoch the same function scores the validation images with gradients switched off.
def run_epoch(data_loader, training):
    model.train(training)  # Dropout is active only in training mode.
    total_loss, total_correct = 0.0, 0
    for images, labels in data_loader:
        images, labels = images.to(DEVICE), labels.to(DEVICE)
        with torch.set_grad_enabled(training):
            logits = model(images)  # 1. Forward pass.
            loss = loss_function(logits, labels)  # 2. Loss.
            if training:
                optimizer.zero_grad()
                loss.backward()  # 3. Gradients by backpropagation.
                optimizer.step()  # 4. Weight update.
        total_loss += loss.item() * len(labels)
        total_correct += (logits.argmax(dim=1) == labels).sum().item()
    return total_loss / len(data_loader.dataset), total_correct / len(data_loader.dataset)


history = {"loss": [], "accuracy": [], "val_loss": [], "val_accuracy": []}
for epoch in range(EPOCHS):
    train_loss, train_accuracy = run_epoch(train_loader, training=True)
    validation_loss, validation_accuracy = run_epoch(validation_loader, training=False)
    for key, value in zip(history, (train_loss, train_accuracy, validation_loss, validation_accuracy)):
        history[key].append(value)
    print(
        f"epoch {epoch + 1}/{EPOCHS}: loss={train_loss:.4f}  accuracy={train_accuracy:.4f}  "
        f"val_loss={validation_loss:.4f}  val_accuracy={validation_accuracy:.4f}"
    )
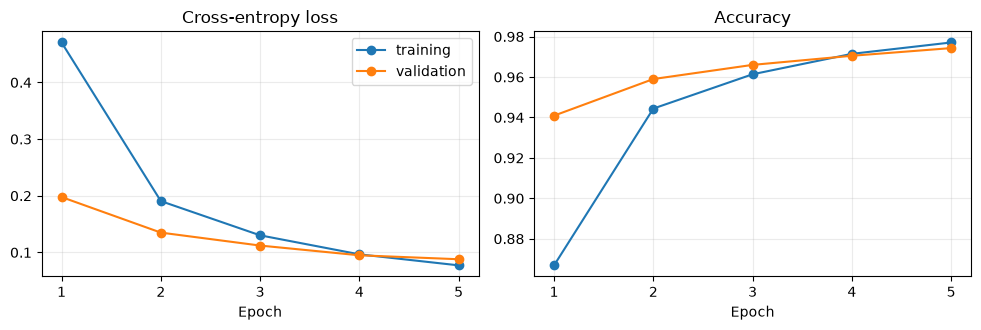
epoch 1/5: loss=0.4705 accuracy=0.8669 val_loss=0.1977 val_accuracy=0.9409
epoch 2/5: loss=0.1905 accuracy=0.9444 val_loss=0.1349 val_accuracy=0.9590
epoch 3/5: loss=0.1301 accuracy=0.9614 val_loss=0.1121 val_accuracy=0.9660
epoch 4/5: loss=0.0966 accuracy=0.9715 val_loss=0.0949 val_accuracy=0.9705
epoch 5/5: loss=0.0771 accuracy=0.9771 val_loss=0.0879 val_accuracy=0.9743
Learning curves#
Training loss falls steadily. If validation loss started to rise while training loss kept falling, the network would be memorizing the training images rather than learning digits in general, which is overfitting. In the first epochs validation accuracy is even higher than training accuracy: dropout is off during validation, and the training figure averages over an epoch in which the weights were still improving.
epochs = np.arange(1, len(history["loss"]) + 1)
fig, axes = plt.subplots(1, 2, figsize=(10, 3.4))
for axis, key, label in zip(axes, ("loss", "accuracy"), ("Cross-entropy loss", "Accuracy")):
    axis.plot(epochs, history[key], marker="o", label="training")
    axis.plot(epochs, history[f"val_{key}"], marker="o", label="validation")
    axis.set(title=label, xlabel="Epoch", xticks=epochs)
    axis.grid(alpha=0.25)
axes[0].legend()
plt.tight_layout()
plt.show()
Evaluate on the test set#
The test images are used once, now that the model is fixed.
test_loss, test_accuracy = run_epoch(test_loader, training=False)
model.eval()
with torch.no_grad():
    test_predictions = model(torch.from_numpy(x_test).to(DEVICE)).argmax(dim=1).cpu().numpy()
cm = confusion_matrix(y_test, test_predictions, labels=np.arange(10))
print(f"test loss: {test_loss:.4f}")
print(f"test accuracy: {test_accuracy:.4f}")
print(classification_report(y_test, test_predictions, digits=3, zero_division=0))
test loss: 0.0853
test accuracy: 0.9740
              precision    recall  f1-score   support

           0      0.978     0.993     0.985       980
           1      0.989     0.989     0.989      1135
           2      0.968     0.982     0.975      1032
           3      0.951     0.979     0.965      1010
           4      0.977     0.968     0.973       982
           5      0.982     0.969     0.975       892
           6      0.983     0.974     0.979       958
           7      0.959     0.977     0.968      1028
           8      0.977     0.953     0.965       974
           9      0.978     0.954     0.966      1009

    accuracy                          0.974     10000
   macro avg      0.974     0.974     0.974     10000
weighted avg      0.974     0.974     0.974     10000
Which digits are confused?#
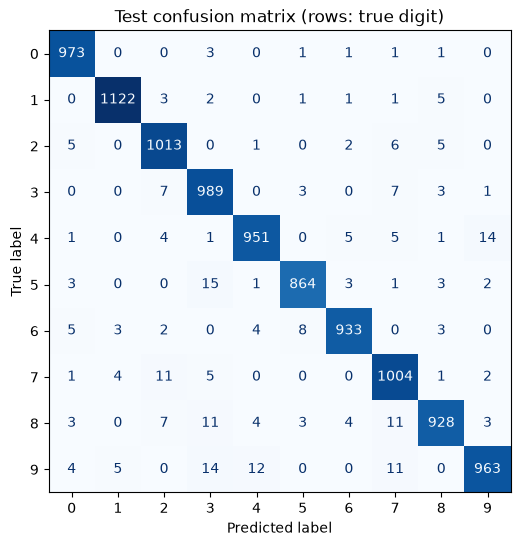
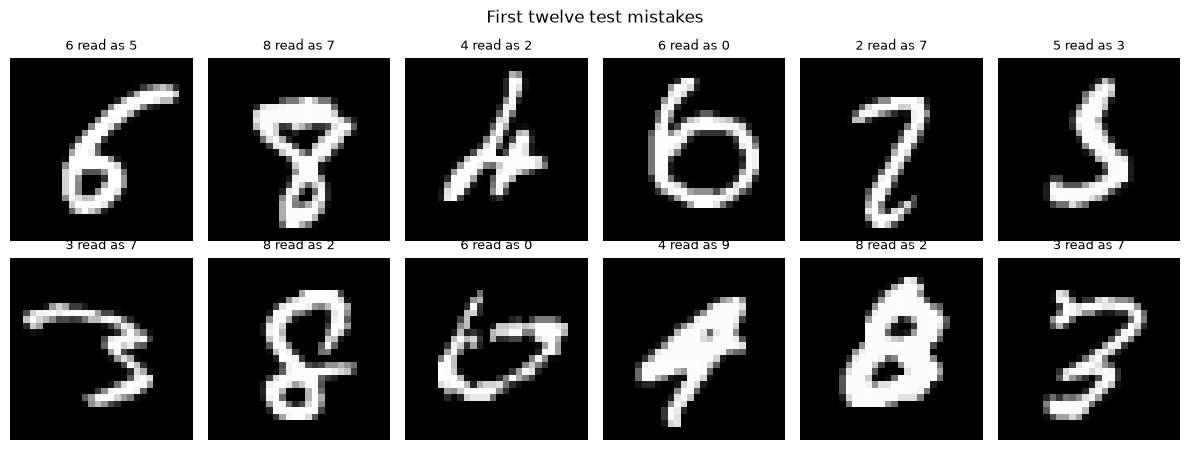
Each row of the confusion matrix is a true digit and each column a predicted one; off-diagonal counts are errors. The images below are the first twelve test mistakes.
fig, ax = plt.subplots(figsize=(6.5, 6))
ConfusionMatrixDisplay(cm, display_labels=np.arange(10)).plot(
    ax=ax, cmap="Blues", colorbar=False
)
ax.set_title("Test confusion matrix (rows: true digit)")
plt.show()

mistakes = np.flatnonzero(test_predictions != y_test)[:12]
fig, axes = plt.subplots(2, 6, figsize=(12, 4.6))
for axis, index in zip(axes.flat, mistakes):
    axis.imshow(x_test[index], cmap="gray")
    axis.set_title(f"{y_test[index]} read as {test_predictions[index]}", fontsize=9)
    axis.axis("off")
fig.suptitle("First twelve test mistakes")
plt.tight_layout()
plt.show()
What the results show#
The network reads about 97.5 of every 100 test digits correctly. Its errors concentrate on a few pairs of similar shapes, and some of the mistakes shown above are hard for a person too. Treating the image as a flat list of pixels discards the fact that neighbouring pixels belong together; the convolutional network uses that structure and makes fewer than half as many errors.
Try it yourself#
Change one choice at a time and keep the data split and evaluation unchanged:
change dropout from
0.5to0.25and compare the gap between training and validation accuracy.halve the width of both hidden layers and compare the parameter count with the change in accuracy.
set the Adam learning rate to
1e-4and to1e-2and compare the learning curves.