SEP Occurrence Forecasting: Repeated Validation#
The data come from Aminalragia-Giamini et al. (2021), who predicted solar energetic particle (SEP) events from soft X-ray flare measurements. Each sample has 49 standardized predictors and a binary label. The archive has no column names, event identifiers, or timestamps, so two limits apply throughout: predictors cannot be interpreted physically, and samples from the same event may fall on both sides of the train/test split.
One train/test split gives one number. This notebook repeats stratified cross-validation within the supplied training set to show how much the scores vary from one partition to the next.
Imports#
Load the data#
The four pickles are downloaded once and checked against their SHA-256 checksums.
verified dataset: sep-curated
  x_train.pkl (checksum verified)
  x_test.pkl (checksum verified)
  y_train.pkl (checksum verified)
  y_test.pkl (checksum verified)
Split and standardize#
The supplied test set is kept for the final evaluation. A stratified 15% of the supplied training samples becomes the validation set. Trees do not need standardized inputs; we standardize anyway so all SEP notebooks share one preprocessing step.
x_supplied_train = pd.read_pickle(dataset_files["x_train.pkl"]).to_numpy(dtype=np.float32)
x_test_raw = pd.read_pickle(dataset_files["x_test.pkl"]).to_numpy(dtype=np.float32)
y_supplied_train = (
    pd.read_pickle(dataset_files["y_train.pkl"]).to_numpy().reshape(-1).astype(np.int64)
)
y_test = pd.read_pickle(dataset_files["y_test.pkl"]).to_numpy().reshape(-1).astype(np.int64)
feature_names = np.asarray([f"feature {i}" for i in range(x_test_raw.shape[1])])

train_indices, validation_indices = train_test_split(
    np.arange(len(y_supplied_train)),
    test_size=0.15,
    random_state=SEED,
    stratify=y_supplied_train,
)
x_train_raw = x_supplied_train[train_indices]
y_train = y_supplied_train[train_indices]
x_validation_raw = x_supplied_train[validation_indices]
y_validation = y_supplied_train[validation_indices]
# Standardize with statistics from the training part only.
scaler = StandardScaler().fit(x_train_raw)
x_train = scaler.transform(x_train_raw).astype(np.float32)
x_validation = scaler.transform(x_validation_raw).astype(np.float32)
x_test = scaler.transform(x_test_raw).astype(np.float32)

counts = np.bincount(y_train, minlength=2)
positive_weight = counts[0] / counts[1]  # About 79 non-events per event.
print(
    f"train={len(y_train):,} ({counts[1]} events), "
    f"validation={len(y_validation):,} ({y_validation.sum()} events), "
    f"test={len(y_test):,} ({y_test.sum()} events)"
)
print(f"event rate in training: {y_train.mean():.4f}; positive-class weight: {positive_weight:.1f}")
train=13,846 (173 events), validation=2,444 (30 events), test=1,811 (23 events)
event rate in training: 0.0125; positive-class weight: 79.0
Verification scores#
SEP events make up about 1.3% of the samples, so a forecast of “no event” is right 98.7% of the time and useless. We therefore report the scores used in space-weather verification, computed from hits, misses, and false alarms:
POD, the probability of detection: the fraction of events forecast.
FAR, the false-alarm ratio: the fraction of event forecasts that were wrong.
TSS = POD minus the probability of false detection. It ranges from −1 to 1 and does not depend on the event rate.
HSS, the Heidke skill score: accuracy relative to random forecasts with the same event rate.
A probabilistic model needs a threshold to issue yes/no forecasts. We choose two on the validation set, one maximizing TSS and one maximizing HSS, and apply both unchanged to the test set. With only 23 test events, a sample-level bootstrap illustrates sampling variability for this fitted model and threshold; it does not account for dependence between samples from the same event.
def verification_scores(y_true, probability, threshold):
    prediction = probability >= threshold
    tn, fp, fn, tp = confusion_matrix(y_true, prediction, labels=[0, 1]).ravel()
    pod = tp / max(tp + fn, 1)  # Probability of detection (recall).
    pofd = fp / max(fp + tn, 1)  # Probability of false detection.
    far = fp / max(tp + fp, 1)  # False-alarm ratio.
    hss_denominator = (tp + fn) * (fn + tn) + (tp + fp) * (fp + tn)
    return {
        "hits": int(tp), "misses": int(fn), "false alarms": int(fp),
        "POD": pod, "FAR": far, "TSS": pod - pofd,
        "HSS": 2 * (tp * tn - fn * fp) / hss_denominator if hss_denominator else 0.0,
    }


def choose_threshold(y_true, probability, score):
    # Test every distinct decision, including all-positive and all-negative.
    # Ascending thresholds resolve equal scores in favour of the lowest threshold.
    candidates = np.append(np.unique(probability), float(np.max(probability)) + 1.0)
    values = [verification_scores(y_true, probability, t)[score] for t in candidates]
    return float(candidates[int(np.argmax(values))])


def bootstrap_intervals(y_true, probability, threshold, repeats=1000):
    # Resample the test set to show how much the scores move with 23 events.
    rng = np.random.default_rng(SEED)
    draws = []
    for _ in range(repeats):
        sample = rng.integers(0, len(y_true), len(y_true))
        if y_true[sample].sum() == 0:
            continue
        scores = verification_scores(y_true[sample], probability[sample], threshold)
        scores["PR-AUC"] = average_precision_score(y_true[sample], probability[sample])
        draws.append(scores)
    draws = pd.DataFrame(draws)[["POD", "FAR", "TSS", "HSS", "PR-AUC"]]
    return draws.quantile([0.025, 0.975]).T.rename(columns={0.025: "2.5%", 0.975: "97.5%"})
Repeated stratified cross-validation#
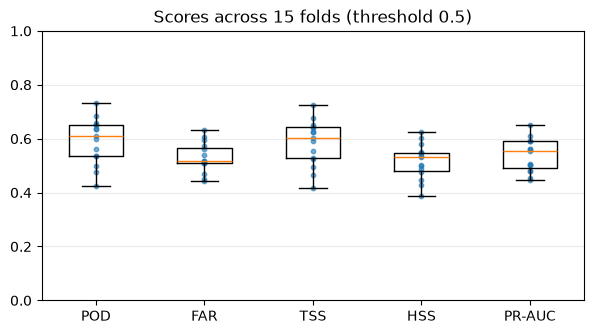
Five folds, repeated three times with different shuffles, give 15 estimates. Each fold approximately preserves the 1.3% event rate. The threshold stays at 0.5; both the partition and the model seed change between fits.
from sklearn.model_selection import RepeatedStratifiedKFold
from xgboost import XGBClassifier

N_SPLITS = 5  # Reduce to 2 for a quicker validation run.
N_REPEATS = 3  # Reduce to 1 for a quicker validation run.
ROUNDS = 200  # Reduce to 20 or 50 for a quicker validation run.
# Repeat the sample-level validation with the same class balance in each fold.
folds = RepeatedStratifiedKFold(
    n_splits=N_SPLITS,
    n_repeats=N_REPEATS,
    random_state=SEED,
)
scores = []
for fold, (fold_train, fold_validation) in enumerate(
    folds.split(x_supplied_train, y_supplied_train), start=1
):
    fold_counts = np.bincount(y_supplied_train[fold_train], minlength=2)
    fold_model = XGBClassifier(
        n_estimators=ROUNDS,
        max_depth=6,
        learning_rate=0.05,
        subsample=0.8,
        colsample_bytree=0.8,
        eval_metric="logloss",
        scale_pos_weight=fold_counts[0] / fold_counts[1],
        random_state=SEED + fold,
        n_jobs=2,
    )
    fold_model.fit(x_supplied_train[fold_train], y_supplied_train[fold_train])
    fold_probability = fold_model.predict_proba(x_supplied_train[fold_validation])[:, 1]
    fold_truth = y_supplied_train[fold_validation]
    score = verification_scores(fold_truth, fold_probability, 0.5)
    score["PR-AUC"] = average_precision_score(fold_truth, fold_probability)
    scores.append(score)

scores = pd.DataFrame(scores, index=pd.RangeIndex(1, len(scores) + 1, name="fold"))
metrics = ["POD", "FAR", "TSS", "HSS", "PR-AUC"]
display(scores[metrics].describe().loc[["mean", "std", "min", "max"]].round(3))

fig, ax = plt.subplots(figsize=(7, 3.5))
ax.boxplot([scores[metric] for metric in metrics], tick_labels=metrics)
for position, metric in enumerate(metrics, start=1):
    ax.scatter(np.full(len(scores), position), scores[metric], s=10, color="tab:blue", alpha=0.6)
ax.set(title=f"Scores across {len(scores)} folds (threshold 0.5)", ylim=(0, 1))
ax.grid(alpha=0.25, axis="y")
plt.show()
| POD | FAR | TSS | HSS | PR-AUC | |
|---|---|---|---|---|---|
| mean | 0.592 | 0.530 | 0.584 | 0.517 | 0.539 |
| std | 0.085 | 0.055 | 0.085 | 0.065 | 0.061 |
| min | 0.425 | 0.444 | 0.416 | 0.387 | 0.449 |
| max | 0.732 | 0.630 | 0.724 | 0.626 | 0.652 |
What the results show#
The spread shows sensitivity to sample partitions and model seeds, not a confidence interval for performance. The folds overlap and are not independent experiments. Without event identifiers, this analysis cannot establish performance on previously unseen events.